Reinforcement learning
AWS DeepRacer / A2RL
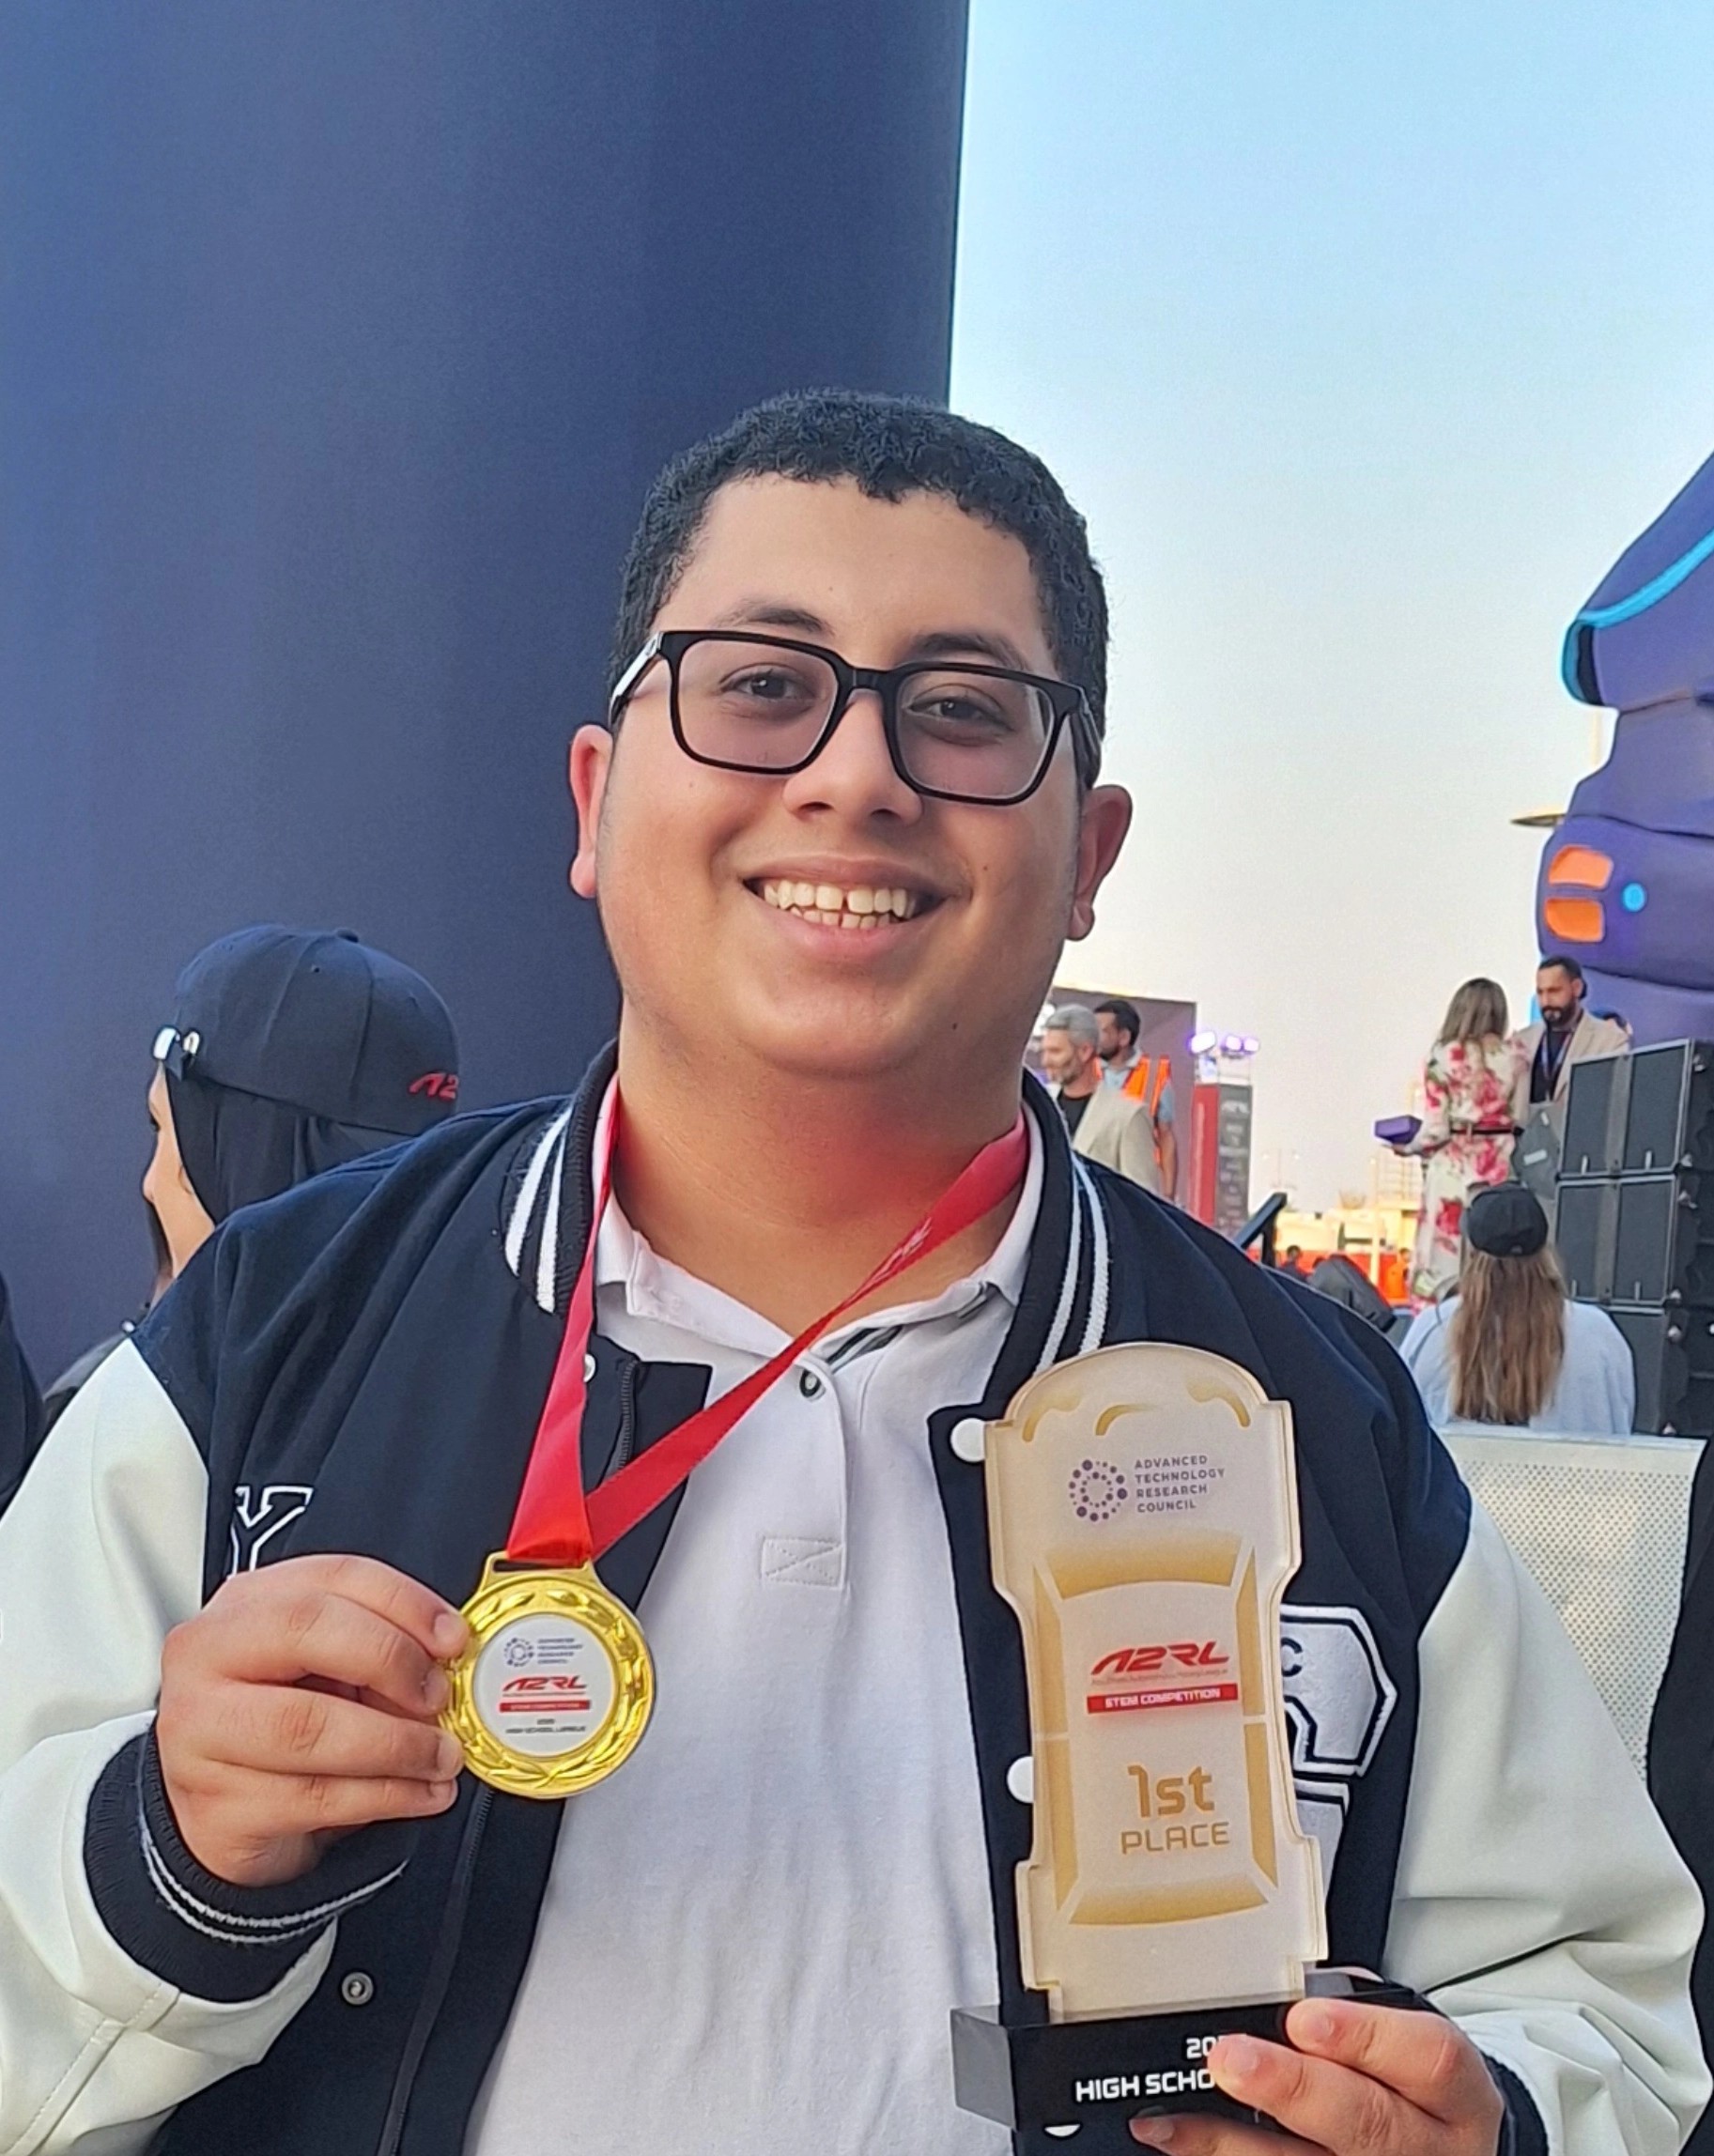
Reward-function design, repeated training, and a first-place finish at the A2RL High School League.
The problem
An autonomous racing model must balance speed with staying on track. I developed and tuned reinforcement-learning models through repeated training and evaluation.
My contribution
- Designed reward functions and tuned model-training parameters.
- Iterated across model versions, using evaluation runs to guide changes.
- Prepared the model for the live A2RL High School League finals.
How it works
The workflow was iterative: define the reward, train, evaluate, and refine. Simulation provided a way to compare models before testing performance on the physical track.
- Reward function
- Training
- Evaluation
- Physical track
The engineering challenge
Performance in simulation does not guarantee the same result on a physical track. The project required balancing faster lap times with consistent completion and making a final model choice with limited physical testing.
Outcome
Won first place in the A2RL High School League with an 8.133-second three-lap average. In the virtual competition, ranked 1st in the UAE, 22nd in MENA, and 330th globally.